Availability & Performance

Availability and performance are engineered, not assumed. We design, monitor and manage infrastructure around what you're running, because business-critical websites, applications and platforms need more than simply being online.

Discover More
Availability & Performance

More Than Uptime

Being online doesn’t always mean everything is working as it should.


Slow performance, infrastructure failures, limited capacity or unexpected demand can all disrupt the applications, websites and platforms your customers rely on.


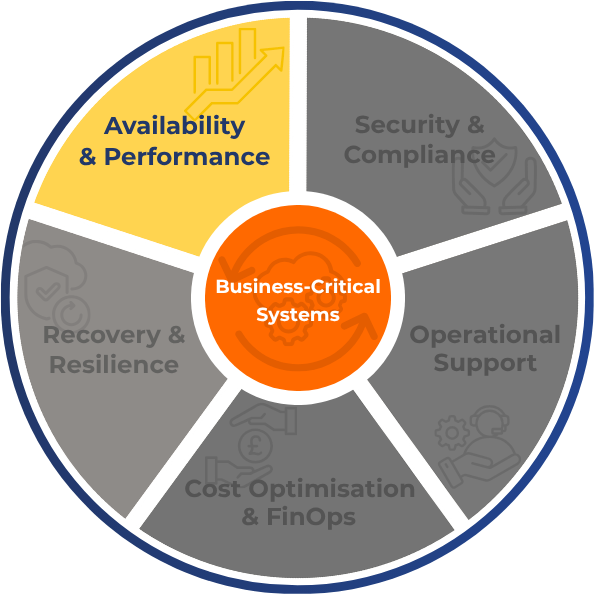
That’s why Availability & Performance is one of five core priorities in our approach to managed cloud. We design, monitor and manage infrastructure around what your technology needs, while considering the security, resilience, support and cost requirements around it.
The Problem

Where availability and performance break down

Our Approach

How we design and manage against it

  • Infrastructure failures cause disruption
  • Design the right level of resilience around what you're running
  • Poor performance affects customers and users
  • Continuously monitor and optimise infrastructure performance
  • Capacity struggles to keep pace with demand
  • Track utilisation and adapt resources to help prevent constraints affecting performance
  • Issues can go unnoticed until customers are affected
  • Proactively monitor, investigate and respond to help prevent problems from escalating.

What Good Looks Like

Good managed cloud is deliberate. Resilience, performance, capacity and monitoring all work together to keep critical systems running properly.

Resilience

Build the right level of protection around what you run, reducing single points of failure so one infrastructure issue does not automatically become an outage.

Performance

Continuously monitor how infrastructure is performing, identify bottlenecks early to help ensure critical systems remain responsive as workloads and demand change.

Capacity

Track resource usage to help maintain enough headroom to support normal operation, unexpected peaks and future growth without performance becoming constrained.

Monitoring

Monitor the infrastructure, services and resources that matter most, so warning signs are identified early and problems can be addressed.

Management

Use monitoring, trends and operational insight to act on what the environment is telling us, rather than waiting for something to fail before responding.

Scalability

Make sure infrastructure can adapt as requirements change, adding or adjusting resources when needed without introducing unnecessary complexity from the outset.

Designed Around What You Need to Run

Good availability and performance do not always need a complex cloud setup.


Sometimes the right answer is a single managed server. Sometimes it is a resilient Azure, AWS, StormCloud or hybrid environment.


We match infrastructure to what you run, how critical it is and the performance it needs. We design for failure, so one problem does not become an outage.


No unnecessary complexity. Just the right level of resilience and performance.

Explore the next principle

Security & Compliance →
0800 817 4727